一、主讲人
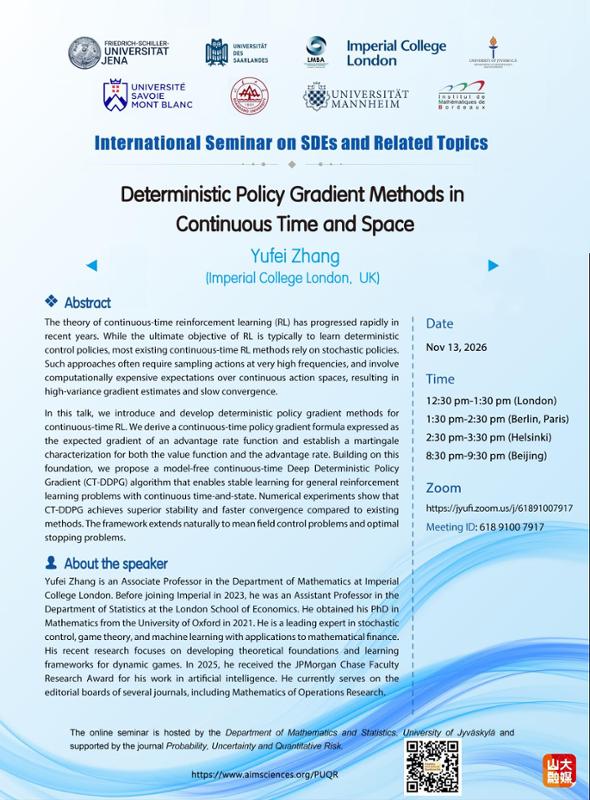
Yufei Zhang,英国帝国理工学院数学系副教授
二、讲座时间
2026年11月13日(星期五)20:30-21:30
三、主讲人简介
Yufei Zhang is an Associate Professor in the Department of Mathematics at Imperial College London. Before joining Imperial in 2023, he was an Assistant Professor in the Department of Statistics at the London School of Economics. He obtained his PhD in Mathematics from the University of Oxford in 2021. He is a leading expert in stochastic control, game theory, and machine learning with applications to mathematical finance. His recent research focuses on developing theoretical foundations and learning frameworks for dynamic games. In 2025, he received the JPMorgan Chase Faculty Research Award for his work in artificial intelligence. He currently serves on the editorial boards of several journals, including Mathematics of Operations Research.
四、报告摘要
The theory of continuous-time reinforcement learning (RL) has progressed rapidly in recent years. While the ultimate objective of RL is typically to learn deterministic control policies, most existing continuous-time RL methods rely on stochastic policies. Such approaches often require sampling actions at very high frequencies, and involve computationally expensive expectations over continuous action spaces, resulting in high-variance gradient estimates and slow convergence.
In this talk, we introduce and develop deterministic policy gradient methods for continuous-time RL. We derive a continuous-time policy gradient formula expressed as the expected gradient of an advantage rate function and establish a martingale characterization for both the value function and the advantage rate. Building on this foundation, we propose a model-free continuous-time Deep Deterministic Policy Gradient (CT-DDPG) algorithm that enables stable learning for general reinforcement learning problems with continuous time-and-state. Numerical experiments show that CT-DDPG achieves superior stability and faster convergence compared to existing methods. The framework extends naturally to mean field control problems and optimal stopping problems.
五、参会方式
扫码观看直播